
Latest

Temperature vs top_p: Which Sampling Control to Change
Temperature reshapes token probabilities; top_p cuts the cumulative tail. Change one control at a time.
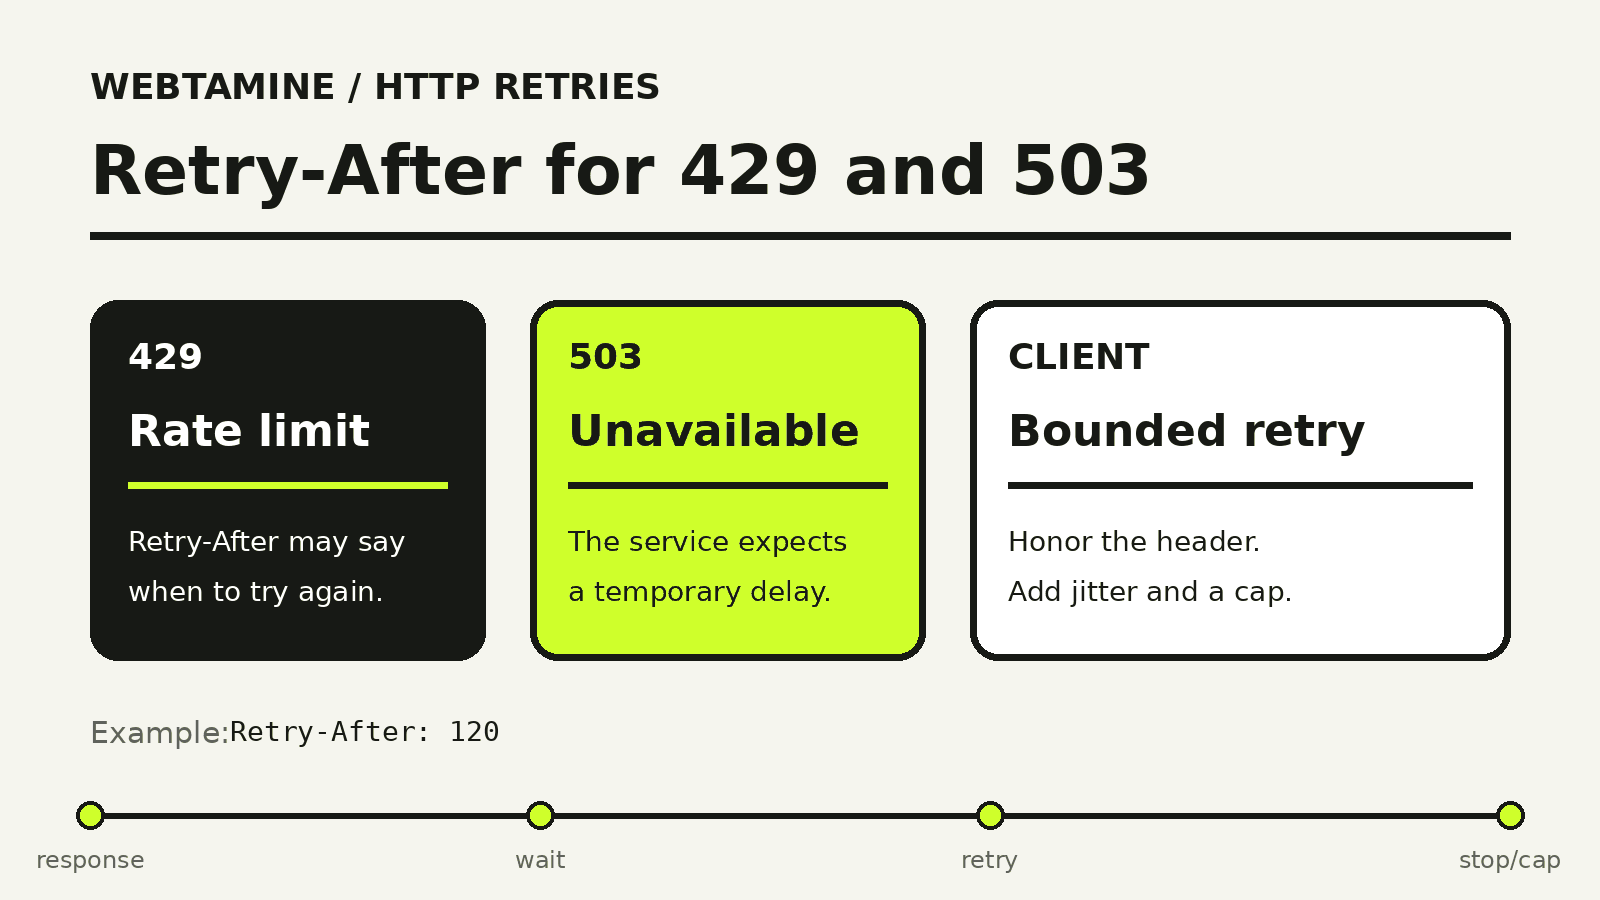
Retry-After for 429 and 503: Build a Safer Client
Parse Retry-After correctly, then combine it with deadlines, jitter, attempt caps and idempotency checks.
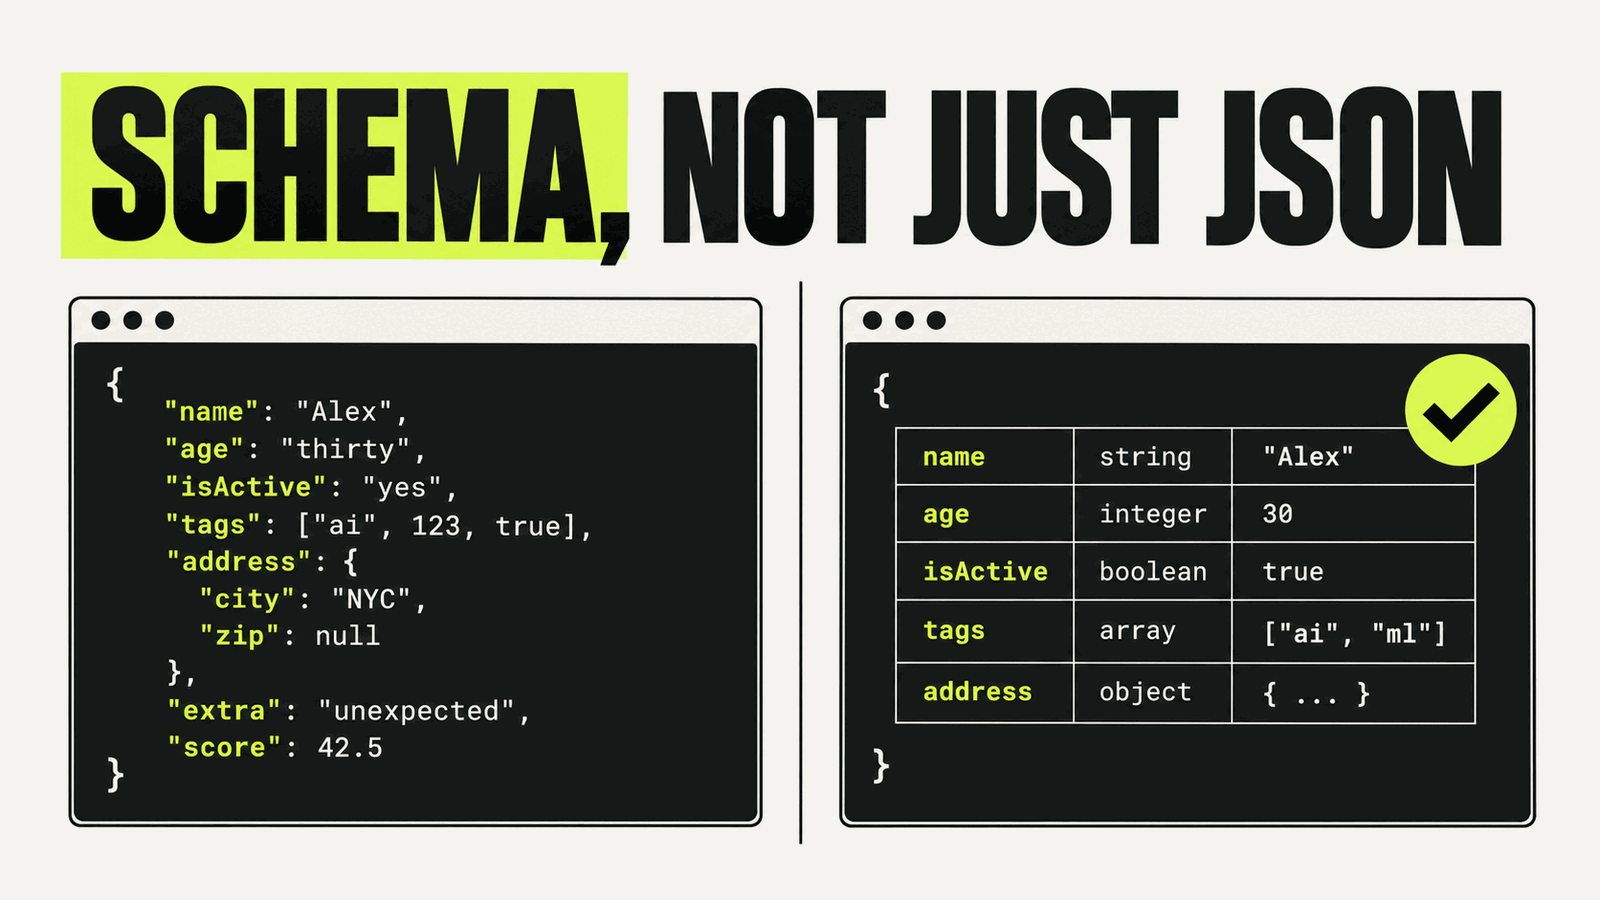
Structured Outputs vs JSON Mode: What the Schema Changes
Choose Structured Outputs or JSON mode by whether valid JSON is enough or every field must follow a schema.
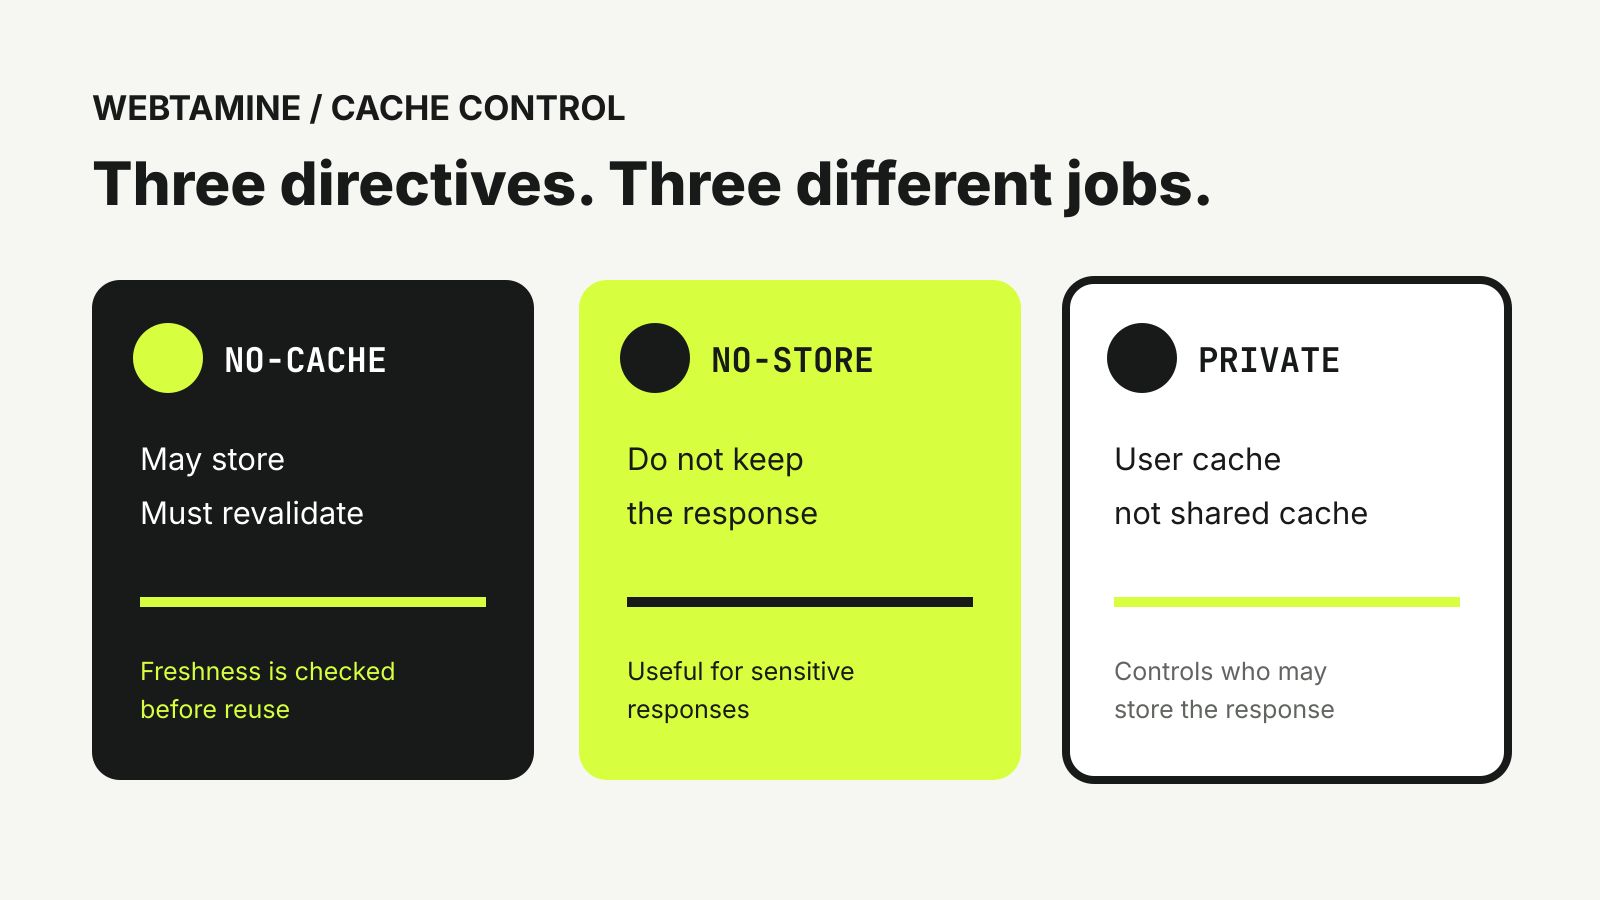
Cache-Control: no-cache vs no-store vs private
Choose no-cache, no-store or private by what may be stored, reused and shared—not by the directive's name.
Claude API Streaming Usage: Count Tokens Once
Record cumulative token counters once, preserve interrupted attempts and separate completion from acceptance.
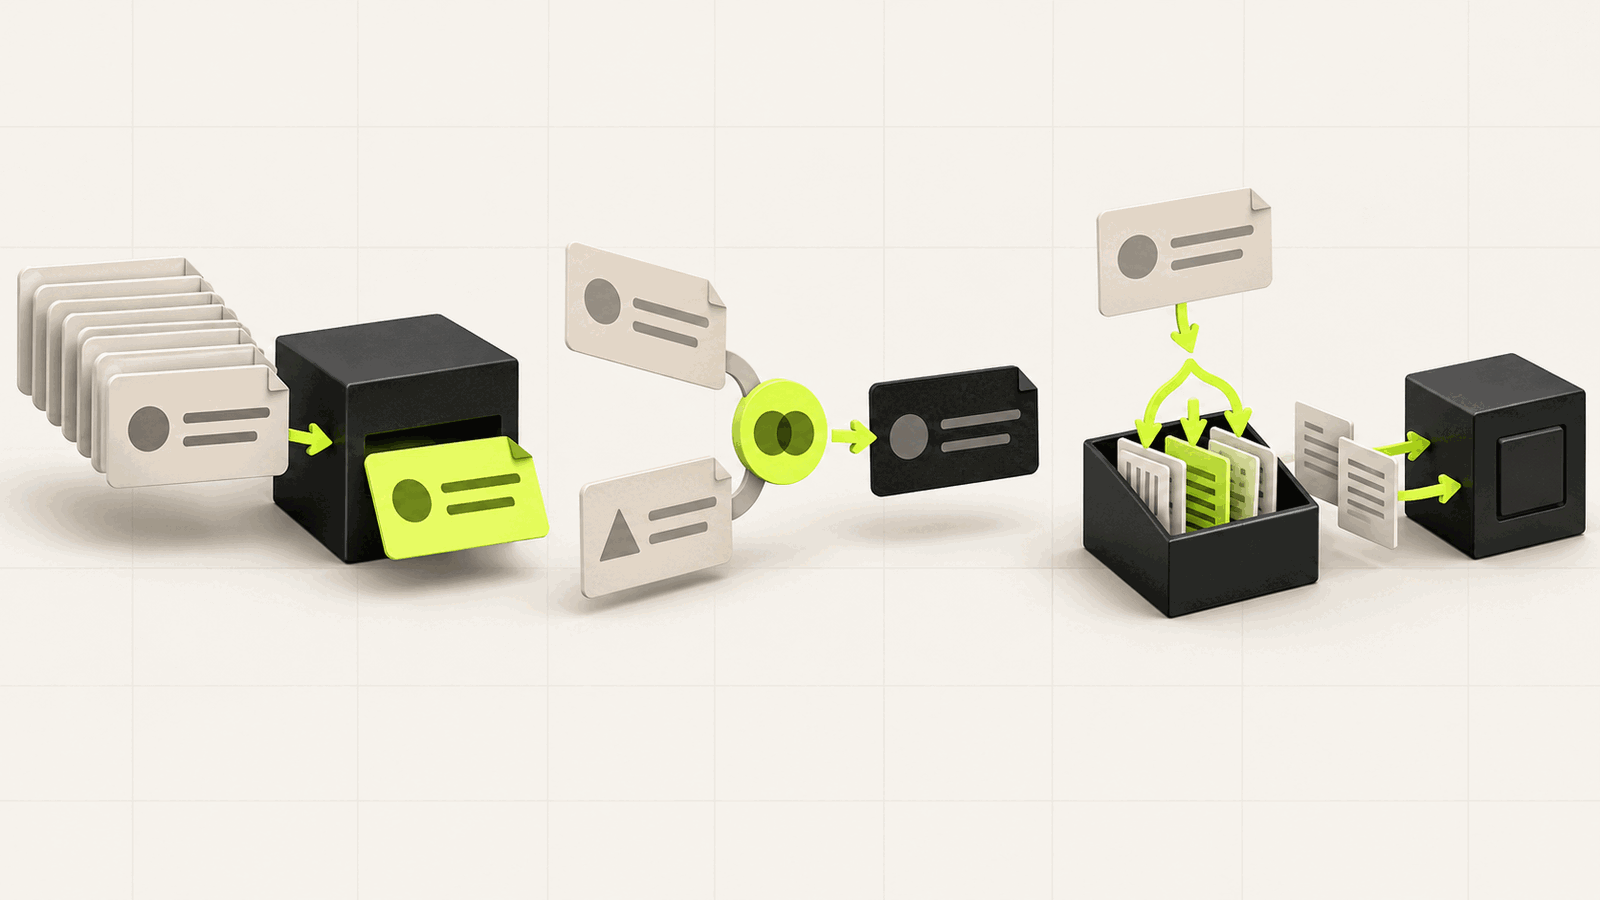
Prompt Caching vs Semantic Caching vs RAG
Prompt caching, semantic caching and RAG reuse different things. Pick the right layer for cost, safety and freshness.
OpenAI API Billing: Why ChatGPT Plans Do Not Include Credits
ChatGPT and the OpenAI API use separate billing. API access needs its own organization, credits and limits.
OpenAI Batch API: Lower Token Costs, Deferred Results
Batch processing discounts eligible API work, while identifiers, error files and expiration need their own handling.
Prompt caching costs: reads, writes and real savings
A worked example of API cache reads, writes and the cost of changing input and generated answers.
Anthropic Tests AI Negotiators in a Book-Swap Market
The agents could bargain. Understanding what their owners wanted was harder.
Open-Weight AI Models: What You Can Use and Change
A model download gives you files. The license tells you what you may do with them.
What an AI Agent Can Do After You Close the Chat
Background work needs more than a model. It needs a place to run and clear limits.
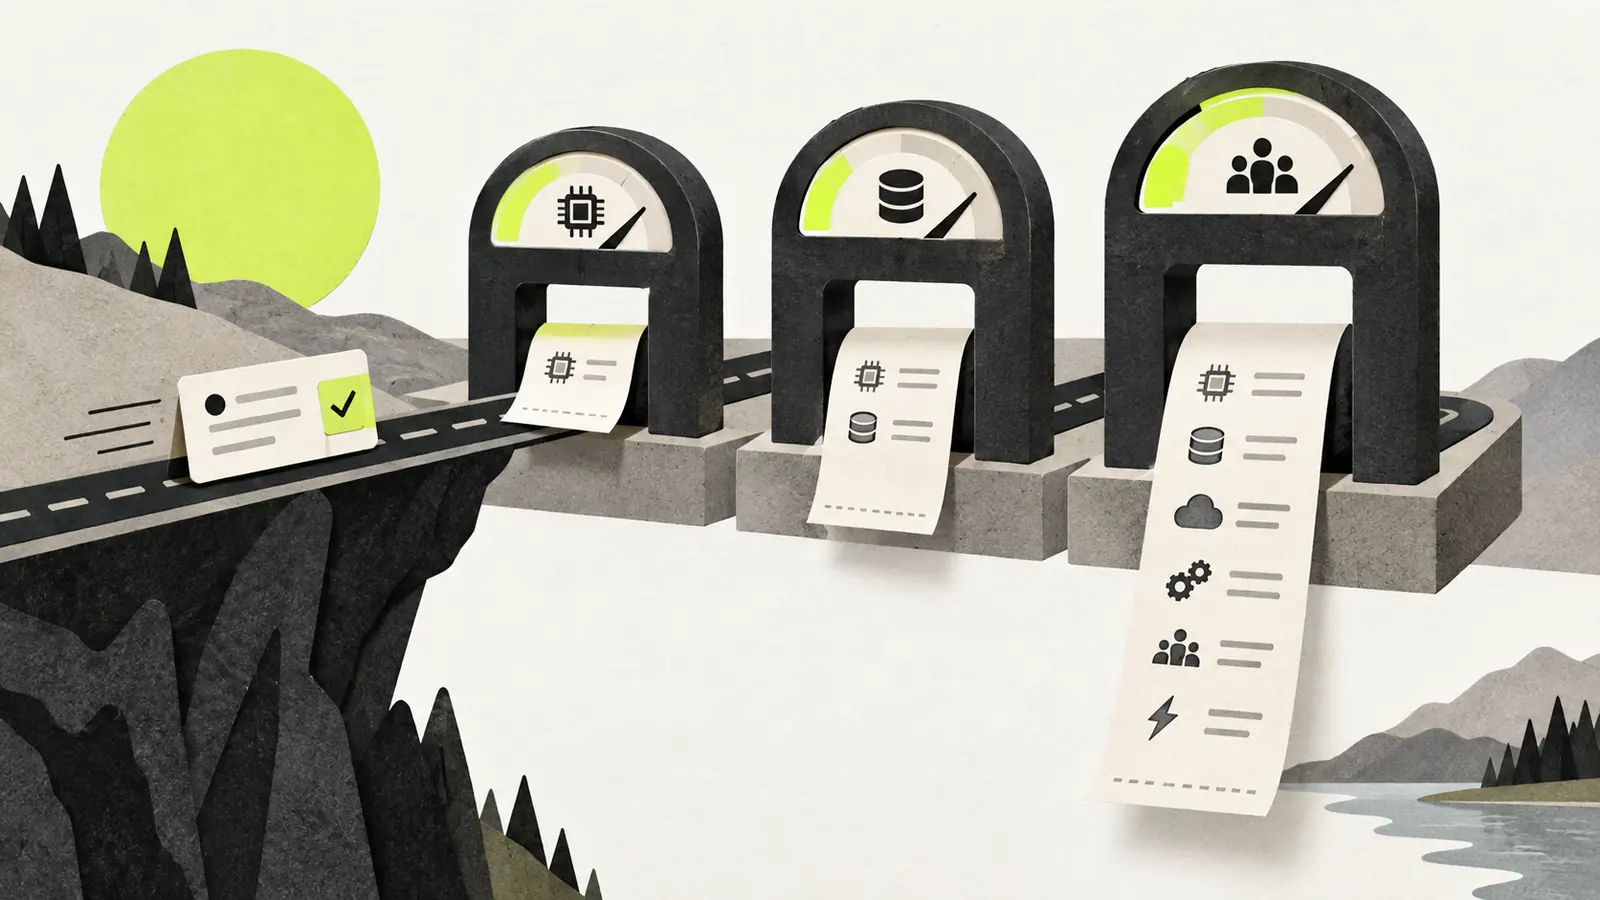
The Cost of an AI Task Goes Beyond the Token Price
Count completed tasks, including retries and review, before comparing model prices.
Liquid AI Brings Its Context Layer to Snapdragon
The software keeps personal context locally and shares relevant information with permitted agents.