
AI
AI models, agents, research and practical applications.

Temperature vs top_p: Which Sampling Control to Change
Temperature reshapes token probabilities; top_p cuts the cumulative tail. Change one control at a time.
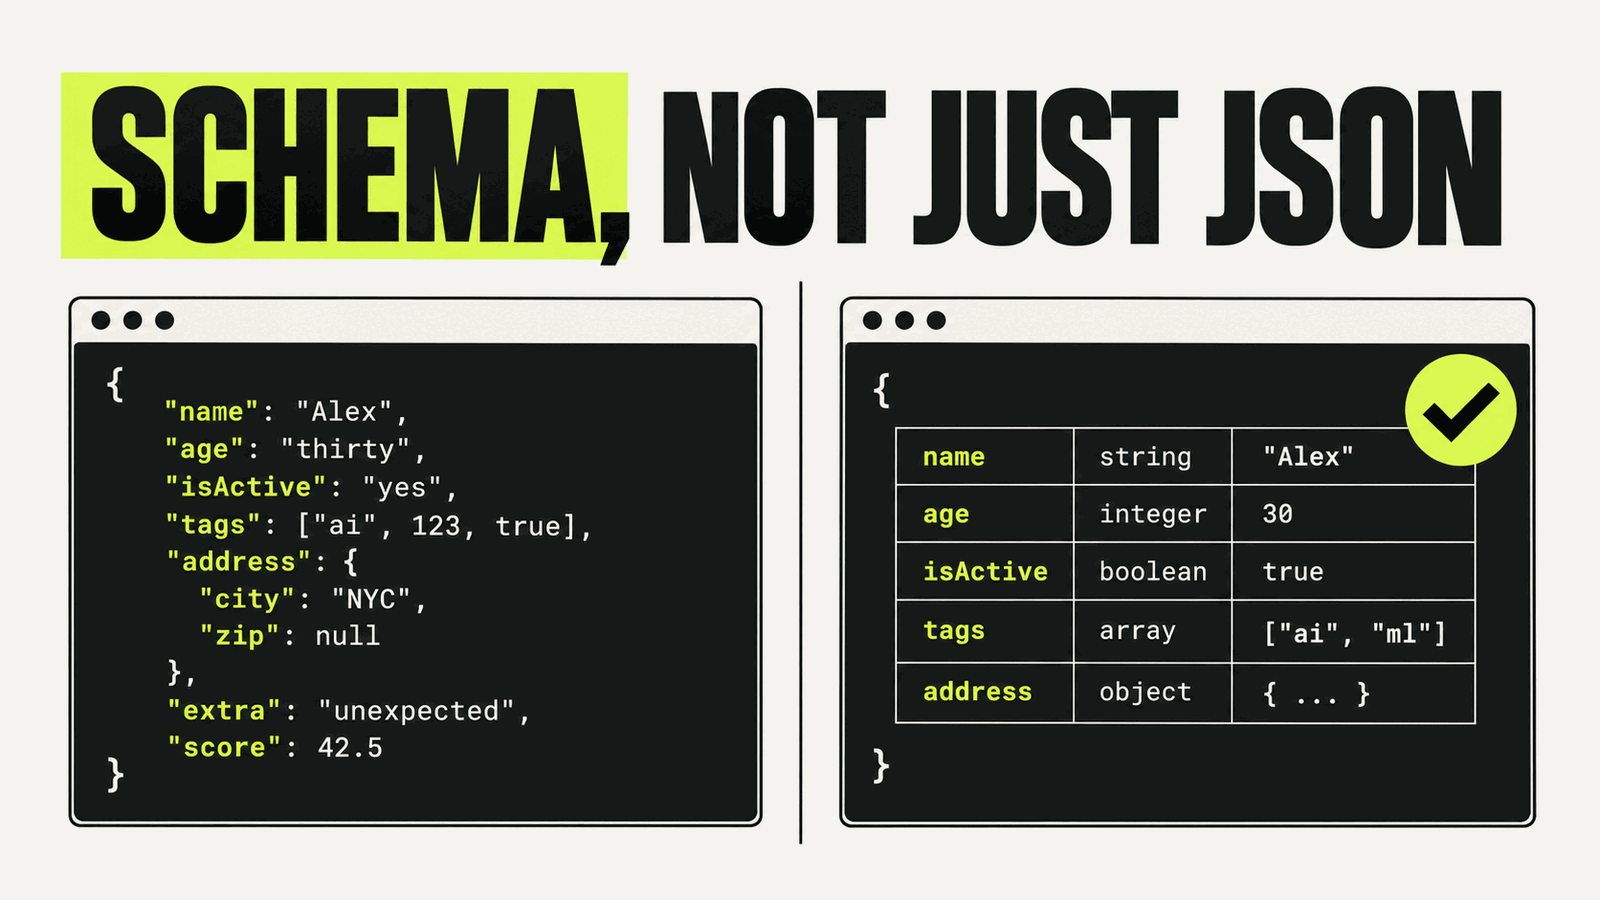
Structured Outputs vs JSON Mode: What the Schema Changes
Choose Structured Outputs or JSON mode by whether valid JSON is enough or every field must follow a schema.
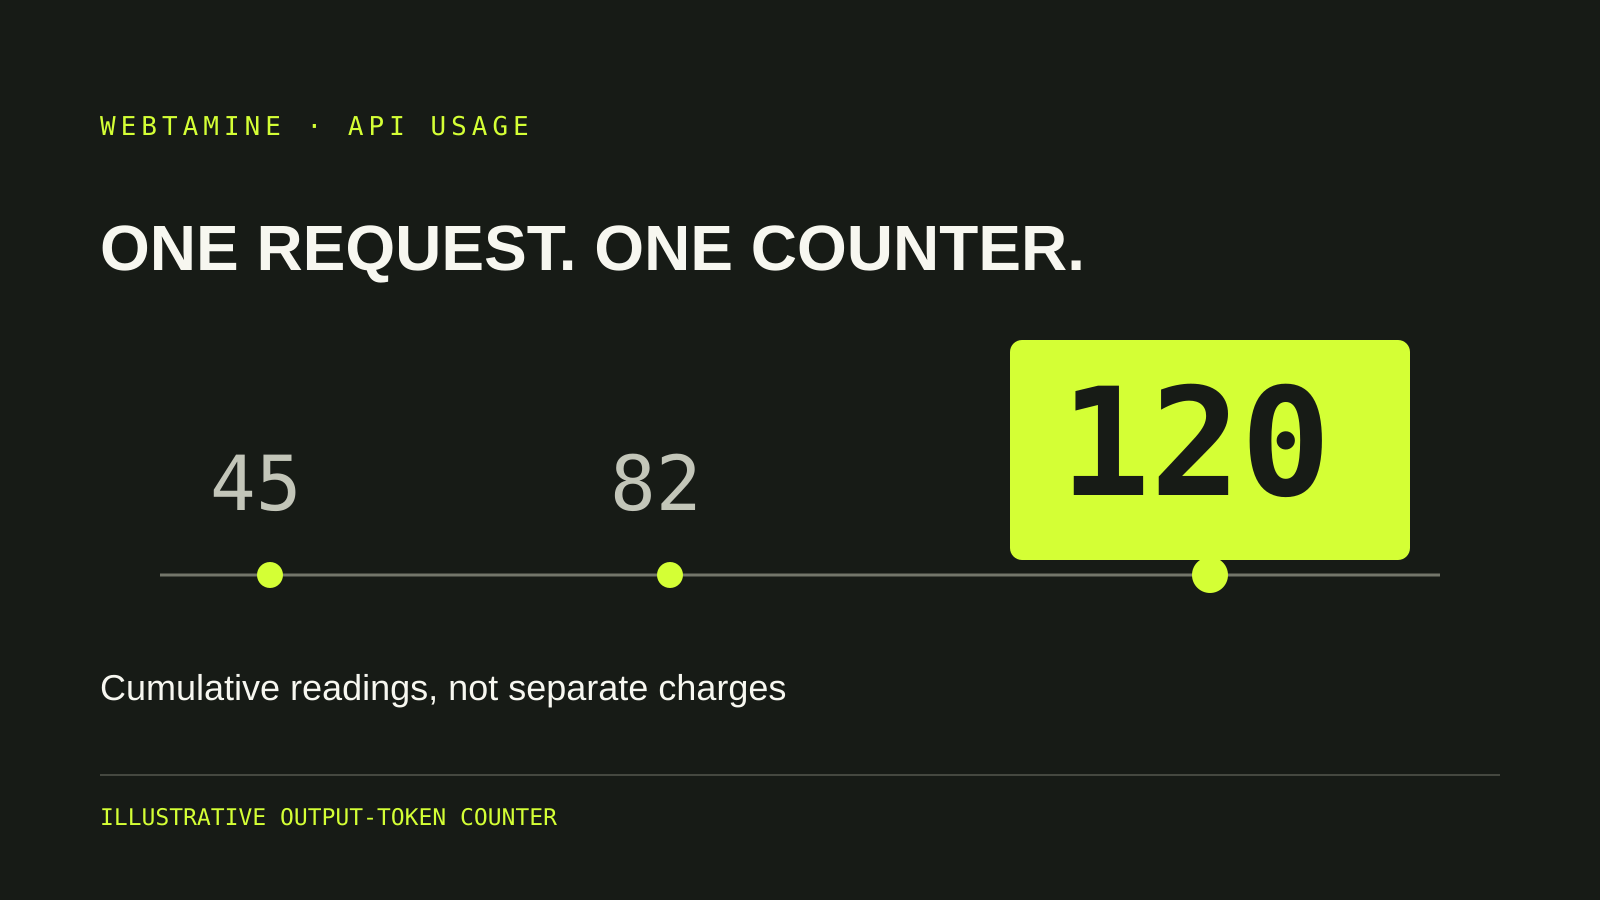
Claude API Streaming Usage: Count Tokens Once
Record cumulative token counters once, preserve interrupted attempts and separate completion from acceptance.
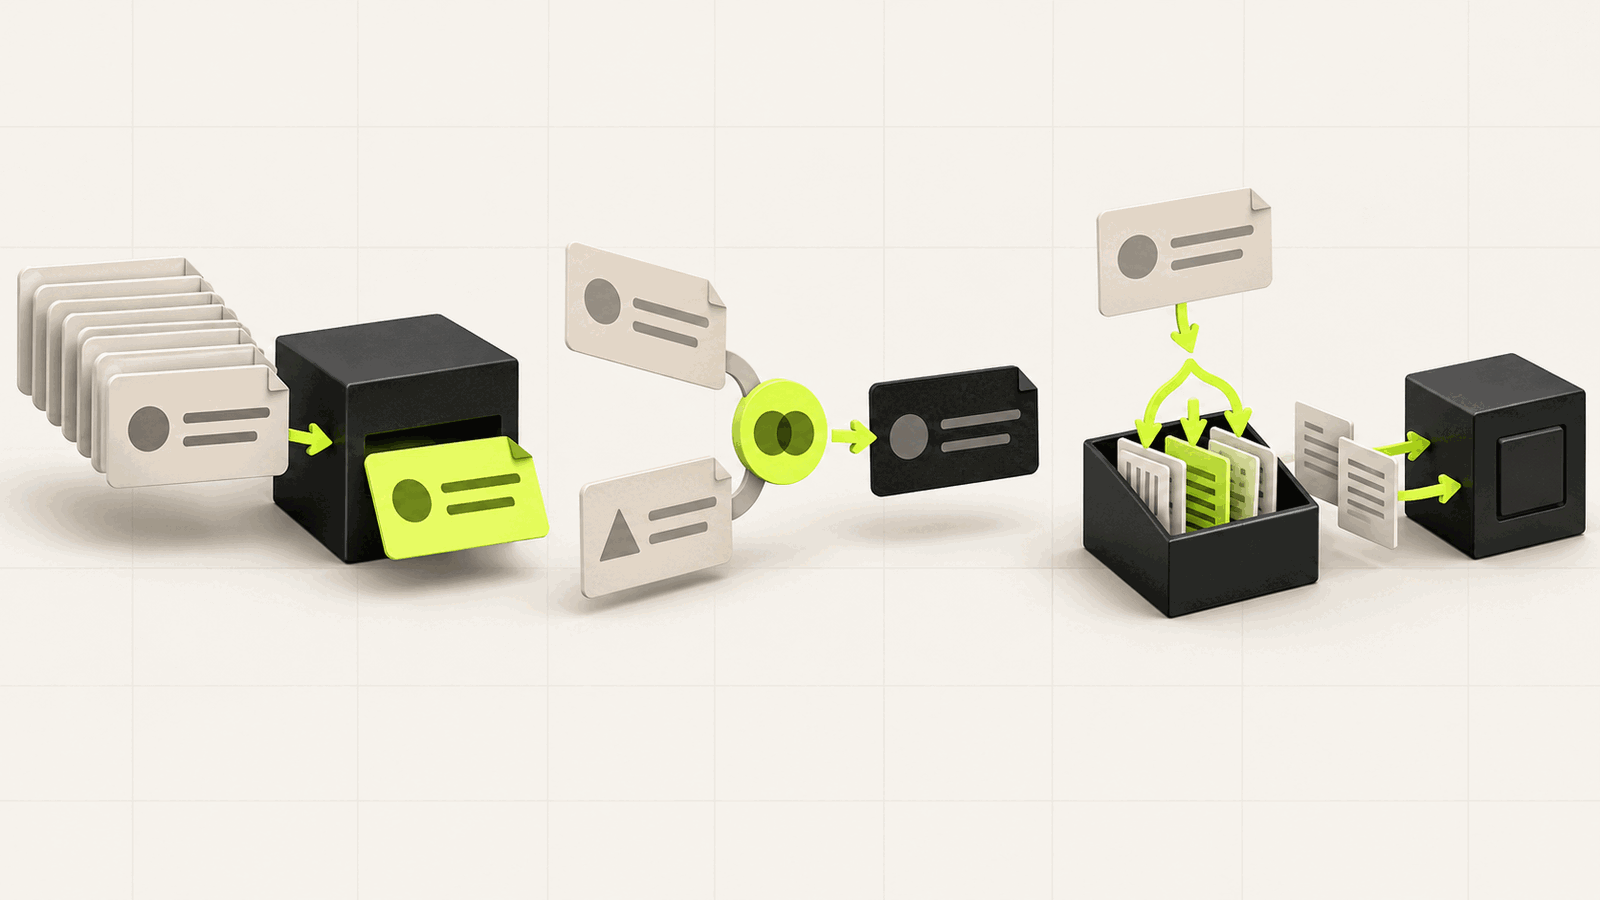
Prompt Caching vs Semantic Caching vs RAG
Prompt caching, semantic caching and RAG reuse different things. Pick the right layer for cost, safety and freshness.
OpenAI API Billing: Why ChatGPT Plans Do Not Include Credits
ChatGPT and the OpenAI API use separate billing. API access needs its own organization, credits and limits.
OpenAI API Rate Limits: Which 429 Errors Can Retry?
A 429 response can mean temporary traffic pressure or an account limit. Read its code before retrying.
OpenAI Batch API: Lower Token Costs, Deferred Results
Batch processing discounts eligible API work, while identifiers, error files and expiration need their own handling.
Prompt caching costs: reads, writes and real savings
A worked example of API cache reads, writes and the cost of changing input and generated answers.
Open-Weight AI Models: What You Can Use and Change
A model download gives you files. The license tells you what you may do with them.
What an AI Agent Can Do After You Close the Chat
Background work needs more than a model. It needs a place to run and clear limits.
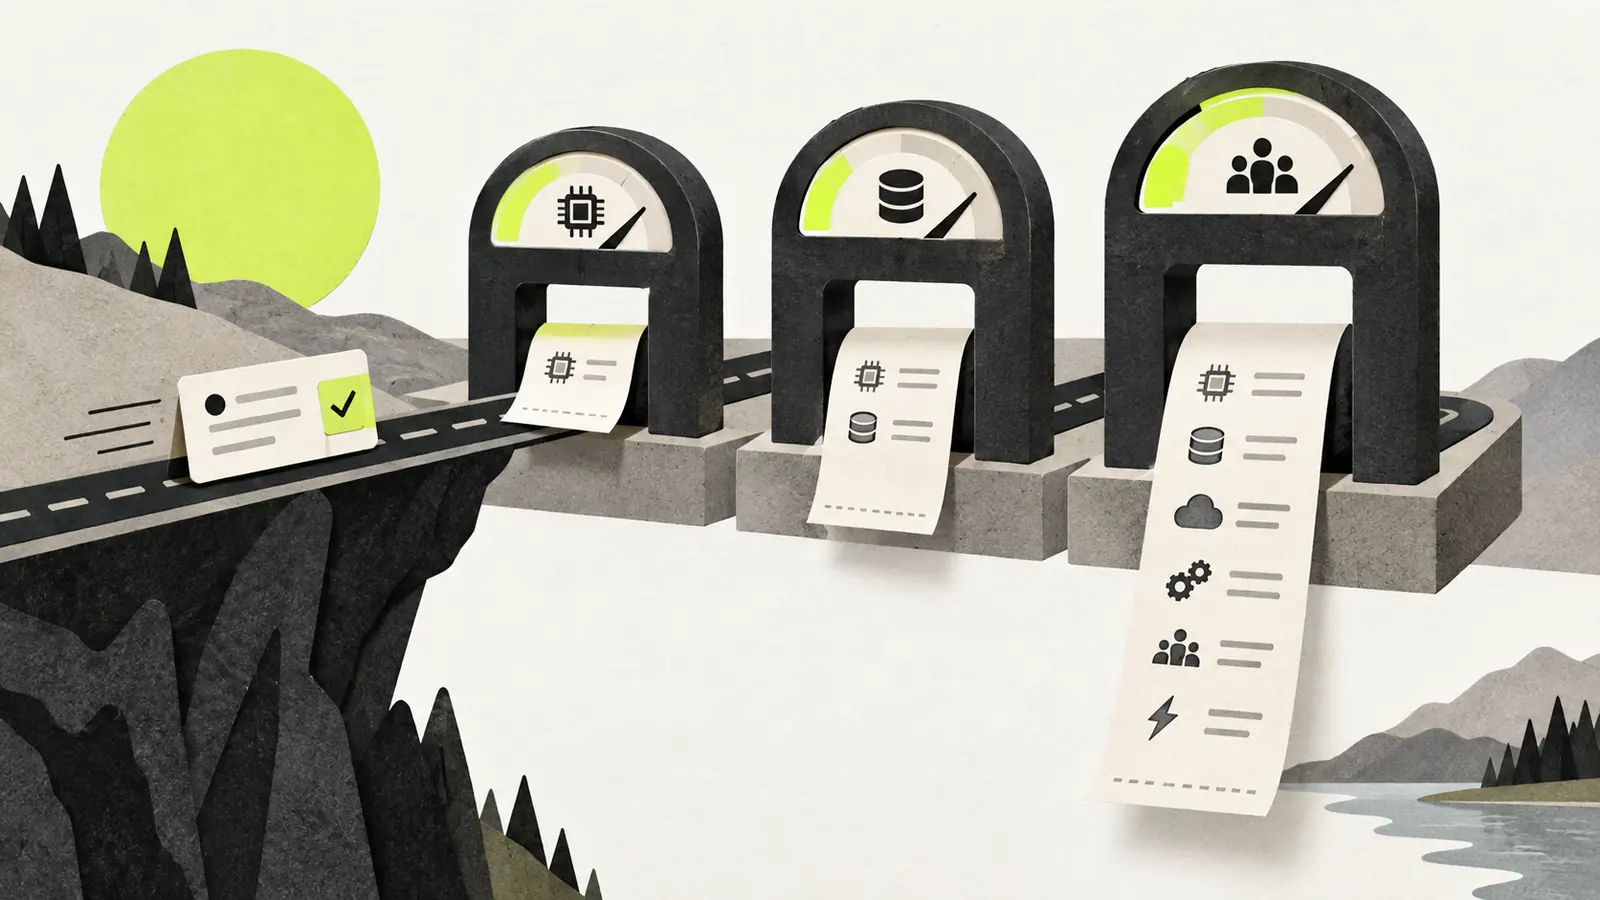
The Cost of an AI Task Goes Beyond the Token Price
Count completed tasks, including retries and review, before comparing model prices.
Understand the components behind an AI product: the model, the tools it can use, the runtime that keeps it active and the checks needed to trust its output. These guides work through concrete tasks rather than assuming that a product label explains the implementation.
Start with background agents, downloadable model weights or the cost of an accepted result. The AI desk connects these longer explanations with current releases and research. Licensing and product behavior should always be checked against the exact version being used.